build 6ddc7a35 | content blog-content@417154f · 338 posts | profiles 32 · corpus 315 | ● 0 skipped | format run

$ soultec get service/monitoring -o yaml$ soultec get service/monitoring -o json$ soultec get service/monitoring -o toml$ soultec get service/monitoring -o xml$ python3 monitoring.pyPS> ./monitoring.ps1$ go run monitoring.go$ node monitoring.js

apiVersion: soultec.ch/v1kind: Servicemetadata: name: monitoring locale: en labels: group: support capability/monitoring: 2.44 capability/managed-services: 2.65 annotations: source: src/content/services/en/monitoring.md route: /en/services/monitoring/ schema: /nerd/schema/services.json markdown: /en/services/monitoring.mdspec: title: Monitoring group: support audience: [enterprise, provider] order: 3 tags: [monitoring, managed-services] summary: >- Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage. photo: monitoring-wall photoNeed: "A monitoring dashboard at 2am tone: dark room, one screen, one person" stub: false draft: false sections: - heading:

The actual problem

body: | Every product, hardware and software alike, can send alerts. That is precisely the difficulty: in a single outage the host, the storage, the database and the application all speak up at once, and in that volume the one message naming the cause gets lost. - heading:

What a monitoring estate has to do

body: | It is made of senders and receivers, and its job is correlation: relating messages to each other so that fifty events become one incident. Only then is analysis possible at all. - heading:

Two kinds, and both are needed

body: | **Proactive monitoring** reports the trend leading to the outage, and so prevents it happening at all. These are mostly the vendors' cloud-based services, which hold your estate against failure patterns seen in very many other installations. **Reactive monitoring** reports that something is broken. These are mostly the on-premises systems, and they are what the alerting sits on top of. Run only the second and you reliably learn about the outage. Run both and you learn about it beforehand. - heading:

What it includes

body: | Hardware, applications, services and networks are monitored, around the clock and without agents on the systems. A dashboard shows the state of the infrastructure, alerting goes by email and SMS, and an alert opens a ticket automatically at the service desk and, where needed, with the vendor. - heading:

What we work with

body: | Our partners' products, or open-source products where those fit better. What suits depends on which interfaces your systems already serve. - heading:

What to watch

body: | Before rollout we settle which message reaches whom and what happens next. Alerts with no agreed response get ignored within weeks, and then they are missing when it counts.status: corpus: 315 solutions: - {ref: solutions/omnissa/workspace-one/workspace-one-assist, score: 0.42} - {ref: solutions/vmware/vmware-cloud-service-provider, score: 0.41} - {ref: solutions/vmware/vmware-cloud-foundation/addon/business-operations, score: 0.40} - {ref: solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon, score: 0.40} alsoLike: - {ref: services/managed-service, score: 1.00} - {ref: services/managed-security, score: 0.52} - {ref: posts/infrastructure-assessment-mit-hpe-cloudphysics, score: 0.49} experts: - {ref: experts/valentina-cicmak, score: 0.42} - {ref: experts/mike-schmid, score: 0.33} - {ref: experts/matthias-frech, score: 0.32} search: /en/search.json
{ "apiVersion": "soultec.ch/v1", "kind": "Service", "metadata": { "name": "monitoring", "locale": "en", "labels": { "group": "support", "capability/monitoring": 2.44, "capability/managed-services": 2.65 }, "annotations": { "source": "src/content/services/en/monitoring.md", "route": "/en/services/monitoring/", "schema": "/nerd/schema/services.json", "markdown": "/en/services/monitoring.md" } }, "spec": { "title": "Monitoring", "group": "support", "audience": [ "enterprise", "provider" ], "order": 3, "tags": [ "monitoring", "managed-services" ], "summary": "Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.", "photo": "monitoring-wall", "photoNeed": "A monitoring dashboard at 2am tone: dark room, one screen, one person", "stub": false, "draft": false, "sections": [ { "heading": "

The actual problem

",
"body": "Every product, hardware and software alike, can send alerts. That is precisely the\ndifficulty: in a single outage the host, the storage, the database and the application all\nspeak up at once, and in that volume the one message naming the cause gets lost." }, { "heading": "

What a monitoring estate has to do

",
"body": "It is made of senders and receivers, and its job is correlation: relating messages to each\nother so that fifty events become one incident. Only then is analysis possible at all." }, { "heading": "

Two kinds, and both are needed

",
"body": "**Proactive monitoring** reports the trend leading to the outage, and so prevents it\nhappening at all. These are mostly the vendors' cloud-based services, which hold your\nestate against failure patterns seen in very many other installations.\n\n**Reactive monitoring** reports that something is broken. These are mostly the on-premises\nsystems, and they are what the alerting sits on top of.\n\nRun only the second and you reliably learn about the outage. Run both and you learn about\nit beforehand." }, { "heading": "

What it includes

",
"body": "Hardware, applications, services and networks are monitored, around the clock and without\nagents on the systems. A dashboard shows the state of the infrastructure, alerting goes by\nemail and SMS, and an alert opens a ticket automatically at the service desk and, where\nneeded, with the vendor." }, { "heading": "

What we work with

",
"body": "Our partners' products, or open-source products where those fit better. What suits depends\non which interfaces your systems already serve." }, { "heading": "

What to watch

",
"body": "Before rollout we settle which message reaches whom and what happens next. Alerts with no\nagreed response get ignored within weeks, and then they are missing when it counts." } ] }, "status": { "corpus": 315, "solutions": [ { "ref": "solutions/omnissa/workspace-one/workspace-one-assist", "score": "0.42" }, { "ref": "solutions/vmware/vmware-cloud-service-provider", "score": "0.41" }, { "ref": "solutions/vmware/vmware-cloud-foundation/addon/business-operations", "score": "0.40" }, { "ref": "solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon", "score": "0.40" } ], "alsoLike": [ { "ref": "services/managed-service", "score": "1.00" }, { "ref": "services/managed-security", "score": "0.52" }, { "ref": "posts/infrastructure-assessment-mit-hpe-cloudphysics", "score": "0.49" } ], "experts": [ { "ref": "experts/valentina-cicmak", "score": "0.42" }, { "ref": "experts/mike-schmid", "score": "0.33" }, { "ref": "experts/matthias-frech", "score": "0.32" } ], "search": "/en/search.json" }}
apiVersion = "soultec.ch/v1"kind = "Service"[metadata]name = "monitoring"locale = "en"[metadata.labels]group = "support""capability/monitoring" = 2.44"capability/managed-services" = 2.65[metadata.annotations]source = "src/content/services/en/monitoring.md"route = "/en/services/monitoring/"schema = "/nerd/schema/services.json"markdown = "/en/services/monitoring.md"[spec]title = "Monitoring"group = "support"audience = ["enterprise", "provider"]order = 3tags = ["monitoring", "managed-services"]summary = "Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage."photo = "monitoring-wall"photoNeed = "A monitoring dashboard at 2am tone: dark room, one screen, one person"stub = falsedraft = false[[spec.sections]]heading = "

The actual problem

"
body = '''Every product, hardware and software alike, can send alerts. That is precisely thedifficulty: in a single outage the host, the storage, the database and the application allspeak up at once, and in that volume the one message naming the cause gets lost.'''[[spec.sections]]heading = "

What a monitoring estate has to do

"
body = '''It is made of senders and receivers, and its job is correlation: relating messages to eachother so that fifty events become one incident. Only then is analysis possible at all.'''[[spec.sections]]heading = "

Two kinds, and both are needed

"
body = '''**Proactive monitoring** reports the trend leading to the outage, and so prevents ithappening at all. These are mostly the vendors' cloud-based services, which hold yourestate against failure patterns seen in very many other installations.**Reactive monitoring** reports that something is broken. These are mostly the on-premisessystems, and they are what the alerting sits on top of.Run only the second and you reliably learn about the outage. Run both and you learn aboutit beforehand.'''[[spec.sections]]heading = "

What it includes

"
body = '''Hardware, applications, services and networks are monitored, around the clock and withoutagents on the systems. A dashboard shows the state of the infrastructure, alerting goes byemail and SMS, and an alert opens a ticket automatically at the service desk and, whereneeded, with the vendor.'''[[spec.sections]]heading = "

What we work with

"
body = '''Our partners' products, or open-source products where those fit better. What suits dependson which interfaces your systems already serve.'''[[spec.sections]]heading = "

What to watch

"
body = '''Before rollout we settle which message reaches whom and what happens next. Alerts with noagreed response get ignored within weeks, and then they are missing when it counts.'''[status]corpus = 315search = "/en/search.json"[[status.solutions]]ref = "solutions/omnissa/workspace-one/workspace-one-assist"score = "0.42"[[status.solutions]]ref = "solutions/vmware/vmware-cloud-service-provider"score = "0.41"[[status.solutions]]ref = "solutions/vmware/vmware-cloud-foundation/addon/business-operations"score = "0.40"[[status.solutions]]ref = "solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon"score = "0.40"[[status.alsoLike]]ref = "services/managed-service"score = "1.00"[[status.alsoLike]]ref = "services/managed-security"score = "0.52"[[status.alsoLike]]ref = "posts/infrastructure-assessment-mit-hpe-cloudphysics"score = "0.49"[[status.experts]]ref = "experts/valentina-cicmak"score = "0.42"[[status.experts]]ref = "experts/mike-schmid"score = "0.33"[[status.experts]]ref = "experts/matthias-frech"score = "0.32"
<?xml version="1.0" encoding="UTF-8"?><manifest kind="Service"> <apiVersion>soultec.ch/v1</apiVersion> <metadata> <name>monitoring</name> <locale>en</locale> <labels> <group>support</group> <entry key="capability/monitoring">2.44</entry> <entry key="capability/managed-services">2.65</entry> </labels> <annotations> <source>src/content/services/en/monitoring.md</source> <route>/en/services/monitoring/</route> <schema>/nerd/schema/services.json</schema> <markdown>/en/services/monitoring.md</markdown> </annotations> </metadata> <spec> <title>Monitoring</title> <group>support</group> <audience> <item>enterprise</item> <item>provider</item> </audience> <order>3</order> <tags> <item>monitoring</item> <item>managed-services</item> </tags> <summary>Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.</summary> <photo>monitoring-wall</photo> <photoNeed>A monitoring dashboard at 2am tone: dark room, one screen, one person</photoNeed> <stub>false</stub> <draft>false</draft> <sections> <section> <heading>

The actual problem

</heading>
<body>Every product, hardware and software alike, can send alerts. That is precisely thedifficulty: in a single outage the host, the storage, the database and the application allspeak up at once, and in that volume the one message naming the cause gets lost. </body> </section> <section> <heading>

What a monitoring estate has to do

</heading>
<body>It is made of senders and receivers, and its job is correlation: relating messages to eachother so that fifty events become one incident. Only then is analysis possible at all. </body> </section> <section> <heading>

Two kinds, and both are needed

</heading>
<body>**Proactive monitoring** reports the trend leading to the outage, and so prevents ithappening at all. These are mostly the vendors' cloud-based services, which hold yourestate against failure patterns seen in very many other installations.**Reactive monitoring** reports that something is broken. These are mostly the on-premisessystems, and they are what the alerting sits on top of.Run only the second and you reliably learn about the outage. Run both and you learn aboutit beforehand. </body> </section> <section> <heading>

What it includes

</heading>
<body>Hardware, applications, services and networks are monitored, around the clock and withoutagents on the systems. A dashboard shows the state of the infrastructure, alerting goes byemail and SMS, and an alert opens a ticket automatically at the service desk and, whereneeded, with the vendor. </body> </section> <section> <heading>

What we work with

</heading>
<body>Our partners' products, or open-source products where those fit better. What suits dependson which interfaces your systems already serve. </body> </section> <section> <heading>

What to watch

</heading>
<body>Before rollout we settle which message reaches whom and what happens next. Alerts with noagreed response get ignored within weeks, and then they are missing when it counts. </body> </section> </sections> </spec> <status> <corpus>315</corpus> <solutions> <item> <ref>solutions/omnissa/workspace-one/workspace-one-assist</ref> <score>0.42</score> </item> <item> <ref>solutions/vmware/vmware-cloud-service-provider</ref> <score>0.41</score> </item> <item> <ref>solutions/vmware/vmware-cloud-foundation/addon/business-operations</ref> <score>0.40</score> </item> <item> <ref>solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon</ref> <score>0.40</score> </item> </solutions> <alsoLike> <item> <ref>services/managed-service</ref> <score>1.00</score> </item> <item> <ref>services/managed-security</ref> <score>0.52</score> </item> <item> <ref>posts/infrastructure-assessment-mit-hpe-cloudphysics</ref> <score>0.49</score> </item> </alsoLike> <experts> <item> <ref>experts/valentina-cicmak</ref> <score>0.42</score> </item> <item> <ref>experts/mike-schmid</ref> <score>0.33</score> </item> <item> <ref>experts/matthias-frech</ref> <score>0.32</score> </item> </experts> <search>/en/search.json</search> </status></manifest>
# Code generated by the soultec.ch build. DO NOT EDIT.import jsonPAGE = { "apiVersion": "soultec.ch/v1", "kind": "Service", "metadata": { "name": "monitoring", "locale": "en", "labels": { "group": "support", "capability/monitoring": 2.44, "capability/managed-services": 2.65, }, "annotations": { "source": "src/content/services/en/monitoring.md", "route": "/en/services/monitoring/", "schema": "/nerd/schema/services.json", "markdown": "/en/services/monitoring.md", }, }, "spec": { "title": "Monitoring", "group": "support", "audience": ["enterprise", "provider"], "order": 3, "tags": ["monitoring", "managed-services"], "summary": "Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.", "photo": "monitoring-wall", "photoNeed": "A monitoring dashboard at 2am tone: dark room, one screen, one person", "stub": False, "draft": False, "sections": [ { "heading": "

The actual problem

",
"body": ( "Every product, hardware and software alike, can send alerts. That is precisely the\n" "difficulty: in a single outage the host, the storage, the database and the application all\n" "speak up at once, and in that volume the one message naming the cause gets lost." ), }, { "heading": "

What a monitoring estate has to do

",
"body": ( "It is made of senders and receivers, and its job is correlation: relating messages to each\n" "other so that fifty events become one incident. Only then is analysis possible at all." ), }, { "heading": "

Two kinds, and both are needed

",
"body": ( "**Proactive monitoring** reports the trend leading to the outage, and so prevents it\n" "happening at all. These are mostly the vendors' cloud-based services, which hold your\n" "estate against failure patterns seen in very many other installations.\n" "\n" "**Reactive monitoring** reports that something is broken. These are mostly the on-premises\n" "systems, and they are what the alerting sits on top of.\n" "\n" "Run only the second and you reliably learn about the outage. Run both and you learn about\n" "it beforehand." ), }, { "heading": "

What it includes

",
"body": ( "Hardware, applications, services and networks are monitored, around the clock and without\n" "agents on the systems. A dashboard shows the state of the infrastructure, alerting goes by\n" "email and SMS, and an alert opens a ticket automatically at the service desk and, where\n" "needed, with the vendor." ), }, { "heading": "

What we work with

",
"body": ( "Our partners' products, or open-source products where those fit better. What suits depends\n" "on which interfaces your systems already serve." ), }, { "heading": "

What to watch

",
"body": ( "Before rollout we settle which message reaches whom and what happens next. Alerts with no\n" "agreed response get ignored within weeks, and then they are missing when it counts." ), }, ], }, "status": { "corpus": 315, "solutions": [ { "ref": "solutions/omnissa/workspace-one/workspace-one-assist", "score": "0.42", }, { "ref": "solutions/vmware/vmware-cloud-service-provider", "score": "0.41", }, { "ref": "solutions/vmware/vmware-cloud-foundation/addon/business-operations", "score": "0.40", }, { "ref": "solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon", "score": "0.40", }, ], "alsoLike": [ { "ref": "services/managed-service", "score": "1.00", }, { "ref": "services/managed-security", "score": "0.52", }, { "ref": "posts/infrastructure-assessment-mit-hpe-cloudphysics", "score": "0.49", }, ], "experts": [ { "ref": "experts/valentina-cicmak", "score": "0.42", }, { "ref": "experts/mike-schmid", "score": "0.33", }, { "ref": "experts/matthias-frech", "score": "0.32", }, ], "search": "/en/search.json", },}if __name__ == "__main__": print(json.dumps(PAGE, indent=2, ensure_ascii=False))
# Code generated by the soultec.ch build. DO NOT EDIT.$Page = [ordered]@{ apiVersion = 'soultec.ch/v1' kind = 'Service' metadata = [ordered]@{ name = 'monitoring' locale = 'en' labels = [ordered]@{ group = 'support' 'capability/monitoring' = 2.44 'capability/managed-services' = 2.65 } annotations = [ordered]@{ source = 'src/content/services/en/monitoring.md' route = '/en/services/monitoring/' schema = '/nerd/schema/services.json' markdown = '/en/services/monitoring.md' } } spec = [ordered]@{ title = 'Monitoring' group = 'support' audience = @('enterprise', 'provider') order = 3 tags = @('monitoring', 'managed-services') summary = 'Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.' photo = 'monitoring-wall' photoNeed = 'A monitoring dashboard at 2am tone: dark room, one screen, one person' stub = $false draft = $false sections = @( [ordered]@{ heading = '

The actual problem

'
body = @'Every product, hardware and software alike, can send alerts. That is precisely thedifficulty: in a single outage the host, the storage, the database and the application allspeak up at once, and in that volume the one message naming the cause gets lost.'@ } [ordered]@{ heading = '

What a monitoring estate has to do

'
body = @'It is made of senders and receivers, and its job is correlation: relating messages to eachother so that fifty events become one incident. Only then is analysis possible at all.'@ } [ordered]@{ heading = '

Two kinds, and both are needed

'
body = @'**Proactive monitoring** reports the trend leading to the outage, and so prevents ithappening at all. These are mostly the vendors' cloud-based services, which hold yourestate against failure patterns seen in very many other installations.**Reactive monitoring** reports that something is broken. These are mostly the on-premisessystems, and they are what the alerting sits on top of.Run only the second and you reliably learn about the outage. Run both and you learn aboutit beforehand.'@ } [ordered]@{ heading = '

What it includes

'
body = @'Hardware, applications, services and networks are monitored, around the clock and withoutagents on the systems. A dashboard shows the state of the infrastructure, alerting goes byemail and SMS, and an alert opens a ticket automatically at the service desk and, whereneeded, with the vendor.'@ } [ordered]@{ heading = '

What we work with

'
body = @'Our partners' products, or open-source products where those fit better. What suits dependson which interfaces your systems already serve.'@ } [ordered]@{ heading = '

What to watch

'
body = @'Before rollout we settle which message reaches whom and what happens next. Alerts with noagreed response get ignored within weeks, and then they are missing when it counts.'@ } ) } status = [ordered]@{ corpus = 315 solutions = @( [ordered]@{ ref = 'solutions/omnissa/workspace-one/workspace-one-assist' score = '0.42' } [ordered]@{ ref = 'solutions/vmware/vmware-cloud-service-provider' score = '0.41' } [ordered]@{ ref = 'solutions/vmware/vmware-cloud-foundation/addon/business-operations' score = '0.40' } [ordered]@{ ref = 'solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon' score = '0.40' } ) alsoLike = @( [ordered]@{ ref = 'services/managed-service' score = '1.00' } [ordered]@{ ref = 'services/managed-security' score = '0.52' } [ordered]@{ ref = 'posts/infrastructure-assessment-mit-hpe-cloudphysics' score = '0.49' } ) experts = @( [ordered]@{ ref = 'experts/valentina-cicmak' score = '0.42' } [ordered]@{ ref = 'experts/mike-schmid' score = '0.33' } [ordered]@{ ref = 'experts/matthias-frech' score = '0.32' } ) search = '/en/search.json' }}$Page | ConvertTo-Json -Depth 32
// Code generated by the soultec.ch build. DO NOT EDIT.package mainimport ( "encoding/json" "os")var page = map[string]any{ "apiVersion": "soultec.ch/v1", "kind": "Service", "metadata": map[string]any{ "name": "monitoring", "locale": "en", "labels": map[string]any{ "group": "support", "capability/monitoring": 2.44, "capability/managed-services": 2.65, }, "annotations": map[string]any{ "source": "src/content/services/en/monitoring.md", "route": "/en/services/monitoring/", "schema": "/nerd/schema/services.json", "markdown": "/en/services/monitoring.md", }, }, "spec": map[string]any{ "title": "Monitoring", "group": "support", "audience": []any{"enterprise", "provider"}, "order": 3, "tags": []any{"monitoring", "managed-services"}, "summary": "Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.", "photo": "monitoring-wall", "photoNeed": "A monitoring dashboard at 2am tone: dark room, one screen, one person", "stub": false, "draft": false, "sections": []any{ map[string]any{ "heading": "

The actual problem

",
"body": "Every product, hardware and software alike, can send alerts. That is precisely the\n" + "difficulty: in a single outage the host, the storage, the database and the application all\n" + "speak up at once, and in that volume the one message naming the cause gets lost.", }, map[string]any{ "heading": "

What a monitoring estate has to do

",
"body": "It is made of senders and receivers, and its job is correlation: relating messages to each\n" + "other so that fifty events become one incident. Only then is analysis possible at all.", }, map[string]any{ "heading": "

Two kinds, and both are needed

",
"body": "**Proactive monitoring** reports the trend leading to the outage, and so prevents it\n" + "happening at all. These are mostly the vendors' cloud-based services, which hold your\n" + "estate against failure patterns seen in very many other installations.\n" + "\n" + "**Reactive monitoring** reports that something is broken. These are mostly the on-premises\n" + "systems, and they are what the alerting sits on top of.\n" + "\n" + "Run only the second and you reliably learn about the outage. Run both and you learn about\n" + "it beforehand.", }, map[string]any{ "heading": "

What it includes

",
"body": "Hardware, applications, services and networks are monitored, around the clock and without\n" + "agents on the systems. A dashboard shows the state of the infrastructure, alerting goes by\n" + "email and SMS, and an alert opens a ticket automatically at the service desk and, where\n" + "needed, with the vendor.", }, map[string]any{ "heading": "

What we work with

",
"body": "Our partners' products, or open-source products where those fit better. What suits depends\n" + "on which interfaces your systems already serve.", }, map[string]any{ "heading": "

What to watch

",
"body": "Before rollout we settle which message reaches whom and what happens next. Alerts with no\n" + "agreed response get ignored within weeks, and then they are missing when it counts.", }, }, }, "status": map[string]any{ "corpus": 315, "solutions": []any{ map[string]any{ "ref": "solutions/omnissa/workspace-one/workspace-one-assist", "score": "0.42", }, map[string]any{ "ref": "solutions/vmware/vmware-cloud-service-provider", "score": "0.41", }, map[string]any{ "ref": "solutions/vmware/vmware-cloud-foundation/addon/business-operations", "score": "0.40", }, map[string]any{ "ref": "solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon", "score": "0.40", }, }, "alsoLike": []any{ map[string]any{ "ref": "services/managed-service", "score": "1.00", }, map[string]any{ "ref": "services/managed-security", "score": "0.52", }, map[string]any{ "ref": "posts/infrastructure-assessment-mit-hpe-cloudphysics", "score": "0.49", }, }, "experts": []any{ map[string]any{ "ref": "experts/valentina-cicmak", "score": "0.42", }, map[string]any{ "ref": "experts/mike-schmid", "score": "0.33", }, map[string]any{ "ref": "experts/matthias-frech", "score": "0.32", }, }, "search": "/en/search.json", },}func main() { enc := json.NewEncoder(os.Stdout) enc.SetEscapeHTML(false) enc.SetIndent("", " ") if err := enc.Encode(page); err != nil { os.Exit(1) }}
// Code generated by the soultec.ch build. DO NOT EDIT.const page = { apiVersion: "soultec.ch/v1", kind: "Service", metadata: { name: "monitoring", locale: "en", labels: { group: "support", "capability/monitoring": 2.44, "capability/managed-services": 2.65, }, annotations: { source: "src/content/services/en/monitoring.md", route: "/en/services/monitoring/", schema: "/nerd/schema/services.json", markdown: "/en/services/monitoring.md", }, }, spec: { title: "Monitoring", group: "support", audience: ["enterprise", "provider"], order: 3, tags: ["monitoring", "managed-services"], summary: "Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.", photo: "monitoring-wall", photoNeed: "A monitoring dashboard at 2am tone: dark room, one screen, one person", stub: false, draft: false, sections: [ { heading: "

The actual problem

",
body: "Every product, hardware and software alike, can send alerts. That is precisely the\n" + "difficulty: in a single outage the host, the storage, the database and the application all\n" + "speak up at once, and in that volume the one message naming the cause gets lost.", }, { heading: "

What a monitoring estate has to do

",
body: "It is made of senders and receivers, and its job is correlation: relating messages to each\n" + "other so that fifty events become one incident. Only then is analysis possible at all.", }, { heading: "

Two kinds, and both are needed

",
body: "**Proactive monitoring** reports the trend leading to the outage, and so prevents it\n" + "happening at all. These are mostly the vendors' cloud-based services, which hold your\n" + "estate against failure patterns seen in very many other installations.\n" + "\n" + "**Reactive monitoring** reports that something is broken. These are mostly the on-premises\n" + "systems, and they are what the alerting sits on top of.\n" + "\n" + "Run only the second and you reliably learn about the outage. Run both and you learn about\n" + "it beforehand.", }, { heading: "

What it includes

",
body: "Hardware, applications, services and networks are monitored, around the clock and without\n" + "agents on the systems. A dashboard shows the state of the infrastructure, alerting goes by\n" + "email and SMS, and an alert opens a ticket automatically at the service desk and, where\n" + "needed, with the vendor.", }, { heading: "

What we work with

",
body: "Our partners' products, or open-source products where those fit better. What suits depends\n" + "on which interfaces your systems already serve.", }, { heading: "

What to watch

",
body: "Before rollout we settle which message reaches whom and what happens next. Alerts with no\n" + "agreed response get ignored within weeks, and then they are missing when it counts.", }, ], }, status: { corpus: 315, solutions: [ { ref: "solutions/omnissa/workspace-one/workspace-one-assist", score: "0.42", }, { ref: "solutions/vmware/vmware-cloud-service-provider", score: "0.41", }, { ref: "solutions/vmware/vmware-cloud-foundation/addon/business-operations", score: "0.40", }, { ref: "solutions/omnissa/workspace-one/addon/omnissa-intelligence-addon", score: "0.40", }, ], alsoLike: [ { ref: "services/managed-service", score: "1.00", }, { ref: "services/managed-security", score: "0.52", }, { ref: "posts/infrastructure-assessment-mit-hpe-cloudphysics", score: "0.49", }, ], experts: [ { ref: "experts/valentina-cicmak", score: "0.42", }, { ref: "experts/mike-schmid", score: "0.33", }, { ref: "experts/matthias-frech", score: "0.32", }, ], search: "/en/search.json", },};console.log(JSON.stringify(page, null, 2));

# 78 lines · YAML · validated at build# 113 lines · JSON · validated at build# 125 lines · TOML · validated at build# 141 lines · XML · validated at build# 141 lines · Python · read back at build, equals the JSON record# 138 lines · PowerShell · read back at build, equals the JSON record# 141 lines · Go · read back at build, equals the JSON record# 126 lines · JavaScript · read back at build, equals the JSON record · served at /en/services/monitoring.md

Service · support

Monitoring

Every system can raise an alert. The skill is relating them to each other rather than receiving fifty messages for one outage.

04Solutions
02Capabilities
315Corpus
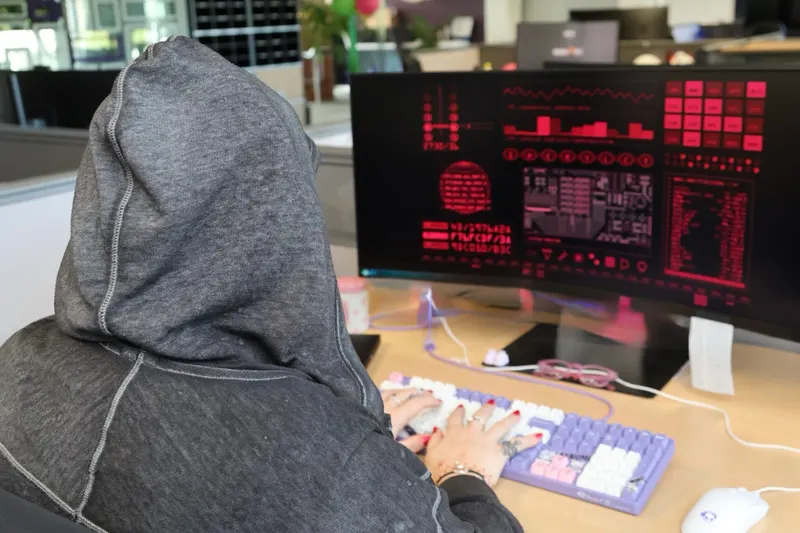
An engineer reading a monitoring dashboard on a dark screen

The actual problem

Every product, hardware and software alike, can send alerts. That is precisely the difficulty: in a single outage the host, the storage, the database and the application all speak up at once, and in that volume the one message naming the cause gets lost.

What a monitoring estate has to do

It is made of senders and receivers, and its job is correlation: relating messages to each other so that fifty events become one incident. Only then is analysis possible at all.

Two kinds, and both are needed

Proactive monitoring reports the trend leading to the outage, and so prevents it happening at all. These are mostly the vendors’ cloud-based services, which hold your estate against failure patterns seen in very many other installations.

Reactive monitoring reports that something is broken. These are mostly the on-premises systems, and they are what the alerting sits on top of.

Run only the second and you reliably learn about the outage. Run both and you learn about it beforehand.

What it includes

Hardware, applications, services and networks are monitored, around the clock and without agents on the systems. A dashboard shows the state of the infrastructure, alerting goes by email and SMS, and an alert opens a ticket automatically at the service desk and, where needed, with the vendor.

What we work with

Our partners’ products, or open-source products where those fit better. What suits depends on which interfaces your systems already serve.

What to watch

Before rollout we settle which message reaches whom and what happens next. Alerts with no agreed response get ignored within weeks, and then they are missing when it counts.
Experts for this

Maybe you? Take a look at our open roles.

You might also like